“Black Budget” — FY 2013 Congressional Budget Justification/National Intelligence Program, pp. 360-364 (February 2012)
Open PDFDocument date: 2012-02-01
Pages: 5
Genre: other
Banner: TOP SECRET//SI/TK//NOFORN
Classification: TOP SECRET SI TK
Dissemination: NOFORN
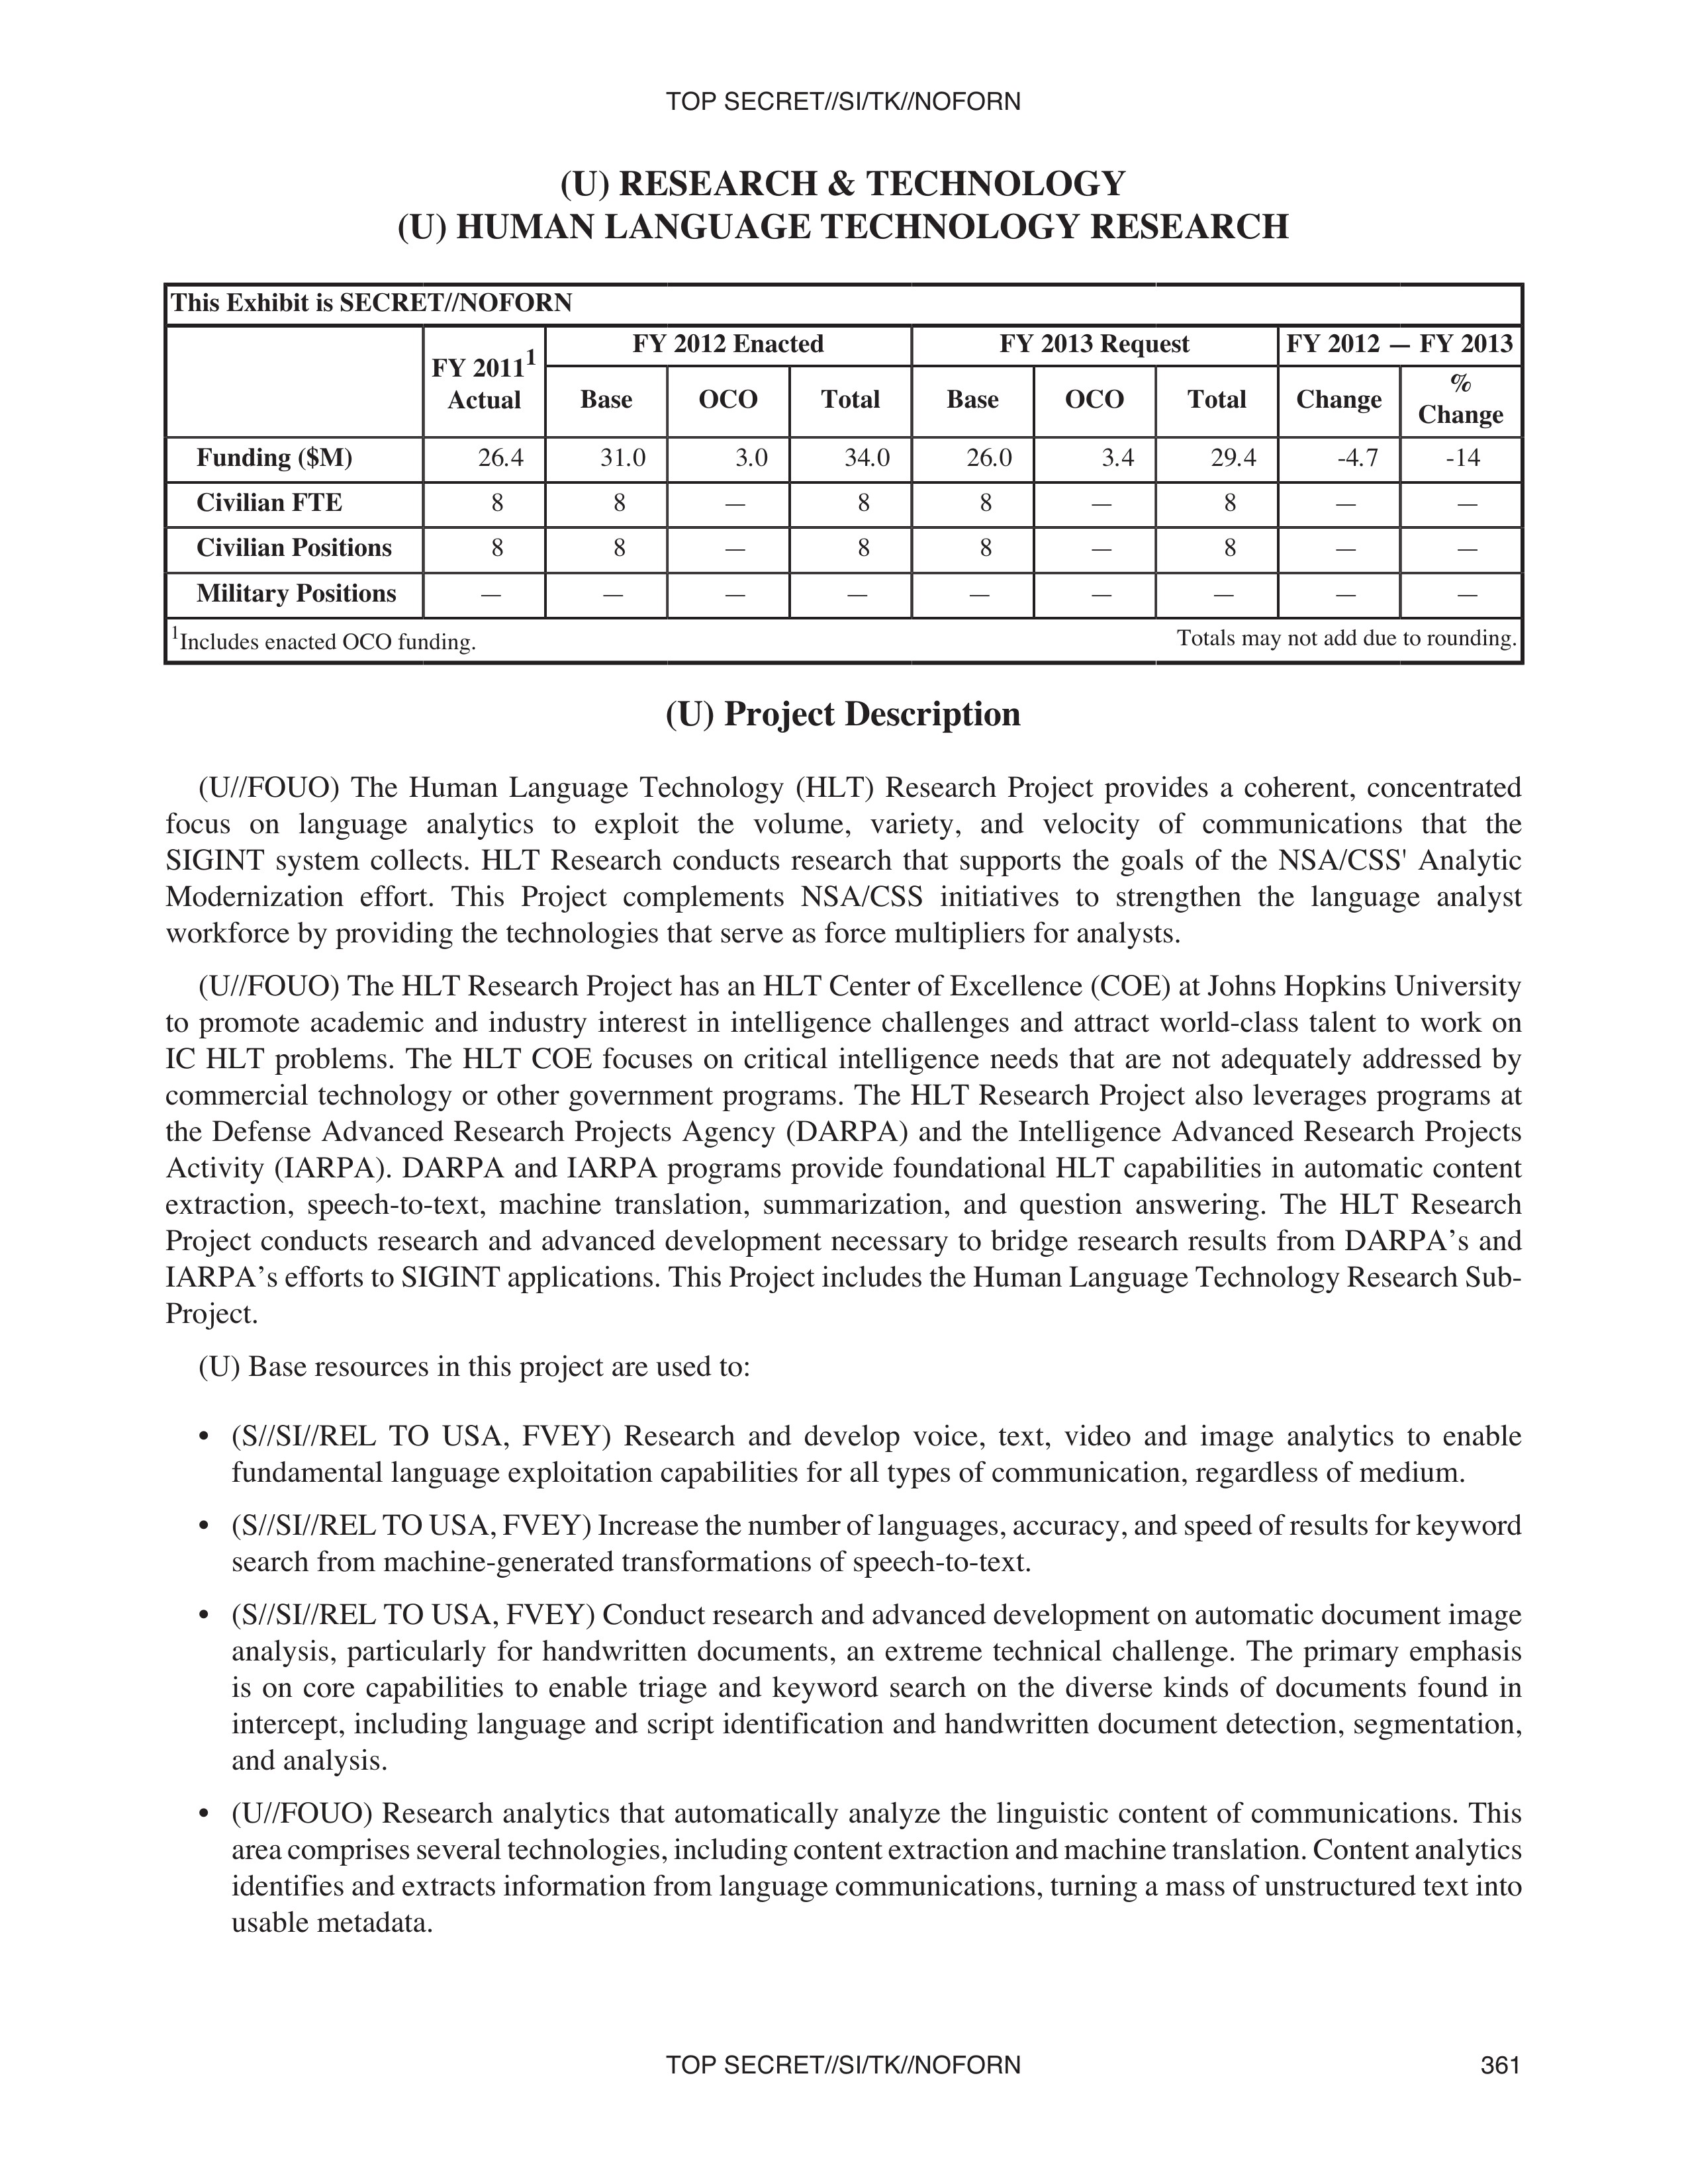
The "Human Language Technology (HLT) Research" section of the FY 2013 "Black Budget" details a specialized research project focused on creating "force multipliers" for the NSA workforce through automated speech-to-text, machine translation, and content extraction. With a requested budget of $29.4 million, the project aims to bridge the gap between foundational academic research (via Johns Hopkins University) and the practical exploitation of the volume and velocity of global SIGINT.
My notes
TOP SECRET//SI/TK//NOFORN
THIS PAGE INTENTIONALLY LEFT BLANK
360
TOP SECRET//SI/TK//NOFORN
TOP SECRET//SI/TK//NOFORN
(U) RESEARCH & TECHNOLOGY
(U) HUMAN LANGUAGE TECHNOLOGY RESEARCH
This Exhibit is SECRET//NOFORN
| FY 2011¹ Actual | FY 2012 Enacted | FY 2013 Request | FY 2012 — | FY 2013 | |||||
|---|---|---|---|---|---|---|---|---|---|
| Base | OCO | Total | Base | OCO | Total | Change | % Change | ||
| Funding ($M) | 26.4 | 31.0 | 3.0 | 34.0 | 26.0 | 3.4 | 29.4 | -4.7 | -14 |
| Civilian FTE | 8 | 8 | 8 | 8 | 8 | ||||
| Civilian Positions | 8 | 8 | 8 | 8 | 8 | ||||
| Military Positions | — | — | — | — | — |
¹ Includes enacted OCO funding.
Totals may not add due to rounding.
(U) Project Description
(U//FOUO) The Human Language Technology (HLT) Research Project provides a coherent, concentrated focus on language analytics to exploit the volume, variety, and velocity of communications that the SIGINT system collects. HLT Research conducts research that supports the goals of the NSA/CSS' Analytic Modernization effort. This Project complements NSA/CSS initiatives to strengthen the language analyst workforce by providing the technologies that serve as force multipliers for analysts.
(U//FOUO) The HLT Research Project has an HLT Center of Excellence (COE) at Johns Hopkins University to promote academic and industry interest in intelligence challenges and attract world-class talent to work on IC HLT problems. The HLT COE focuses on critical intelligence needs that are not adequately addressed by commercial technology or other government programs. The HLT Research Project also leverages programs at the Defense Advanced Research Projects Agency (DARPA) and the Intelligence Advanced Research Projects Activity (IARPA). DARPA and IARPA programs provide foundational HLT capabilities in automatic content extraction, speech-to-text, machine translation, summarization, and question answering. The HLT Research Project conducts research and advanced development necessary to bridge research results from DARPA's and IARPA's efforts to SIGINT applications. This Project includes the Human Language Technology Research Sub-Project.
(U) Base resources in this project are used to:
- (S//SI//REL TO USA, FVEY) Research and develop voice, text, video and image analytics to enable fundamental language exploitation capabilities for all types of communication, regardless of medium.
- (S//SI//REL TO USA, FVEY) Increase the number of languages, accuracy, and speed of results for keyword search from machine-generated transformations of speech-to-text.
- (S//SI//REL TO USA, FVEY) Conduct research and advanced development on automatic document image analysis, particularly for handwritten documents, an extreme technical challenge. The primary emphasis is on core capabilities to enable triage and keyword search on the diverse kinds of documents found in intercept, including language and script identification and handwritten document detection, segmentation, and analysis.
- (U//FOUO) Research analytics that automatically analyze the linguistic content of communications. This area comprises several technologies, including content extraction and machine translation. Content analytics identifies and extracts information from language communications, turning a mass of unstructured text into usable metadata.
TOP SECRET//SI/TK//NOFORN
361
TOP SECRET//SI/TK//NOFORN
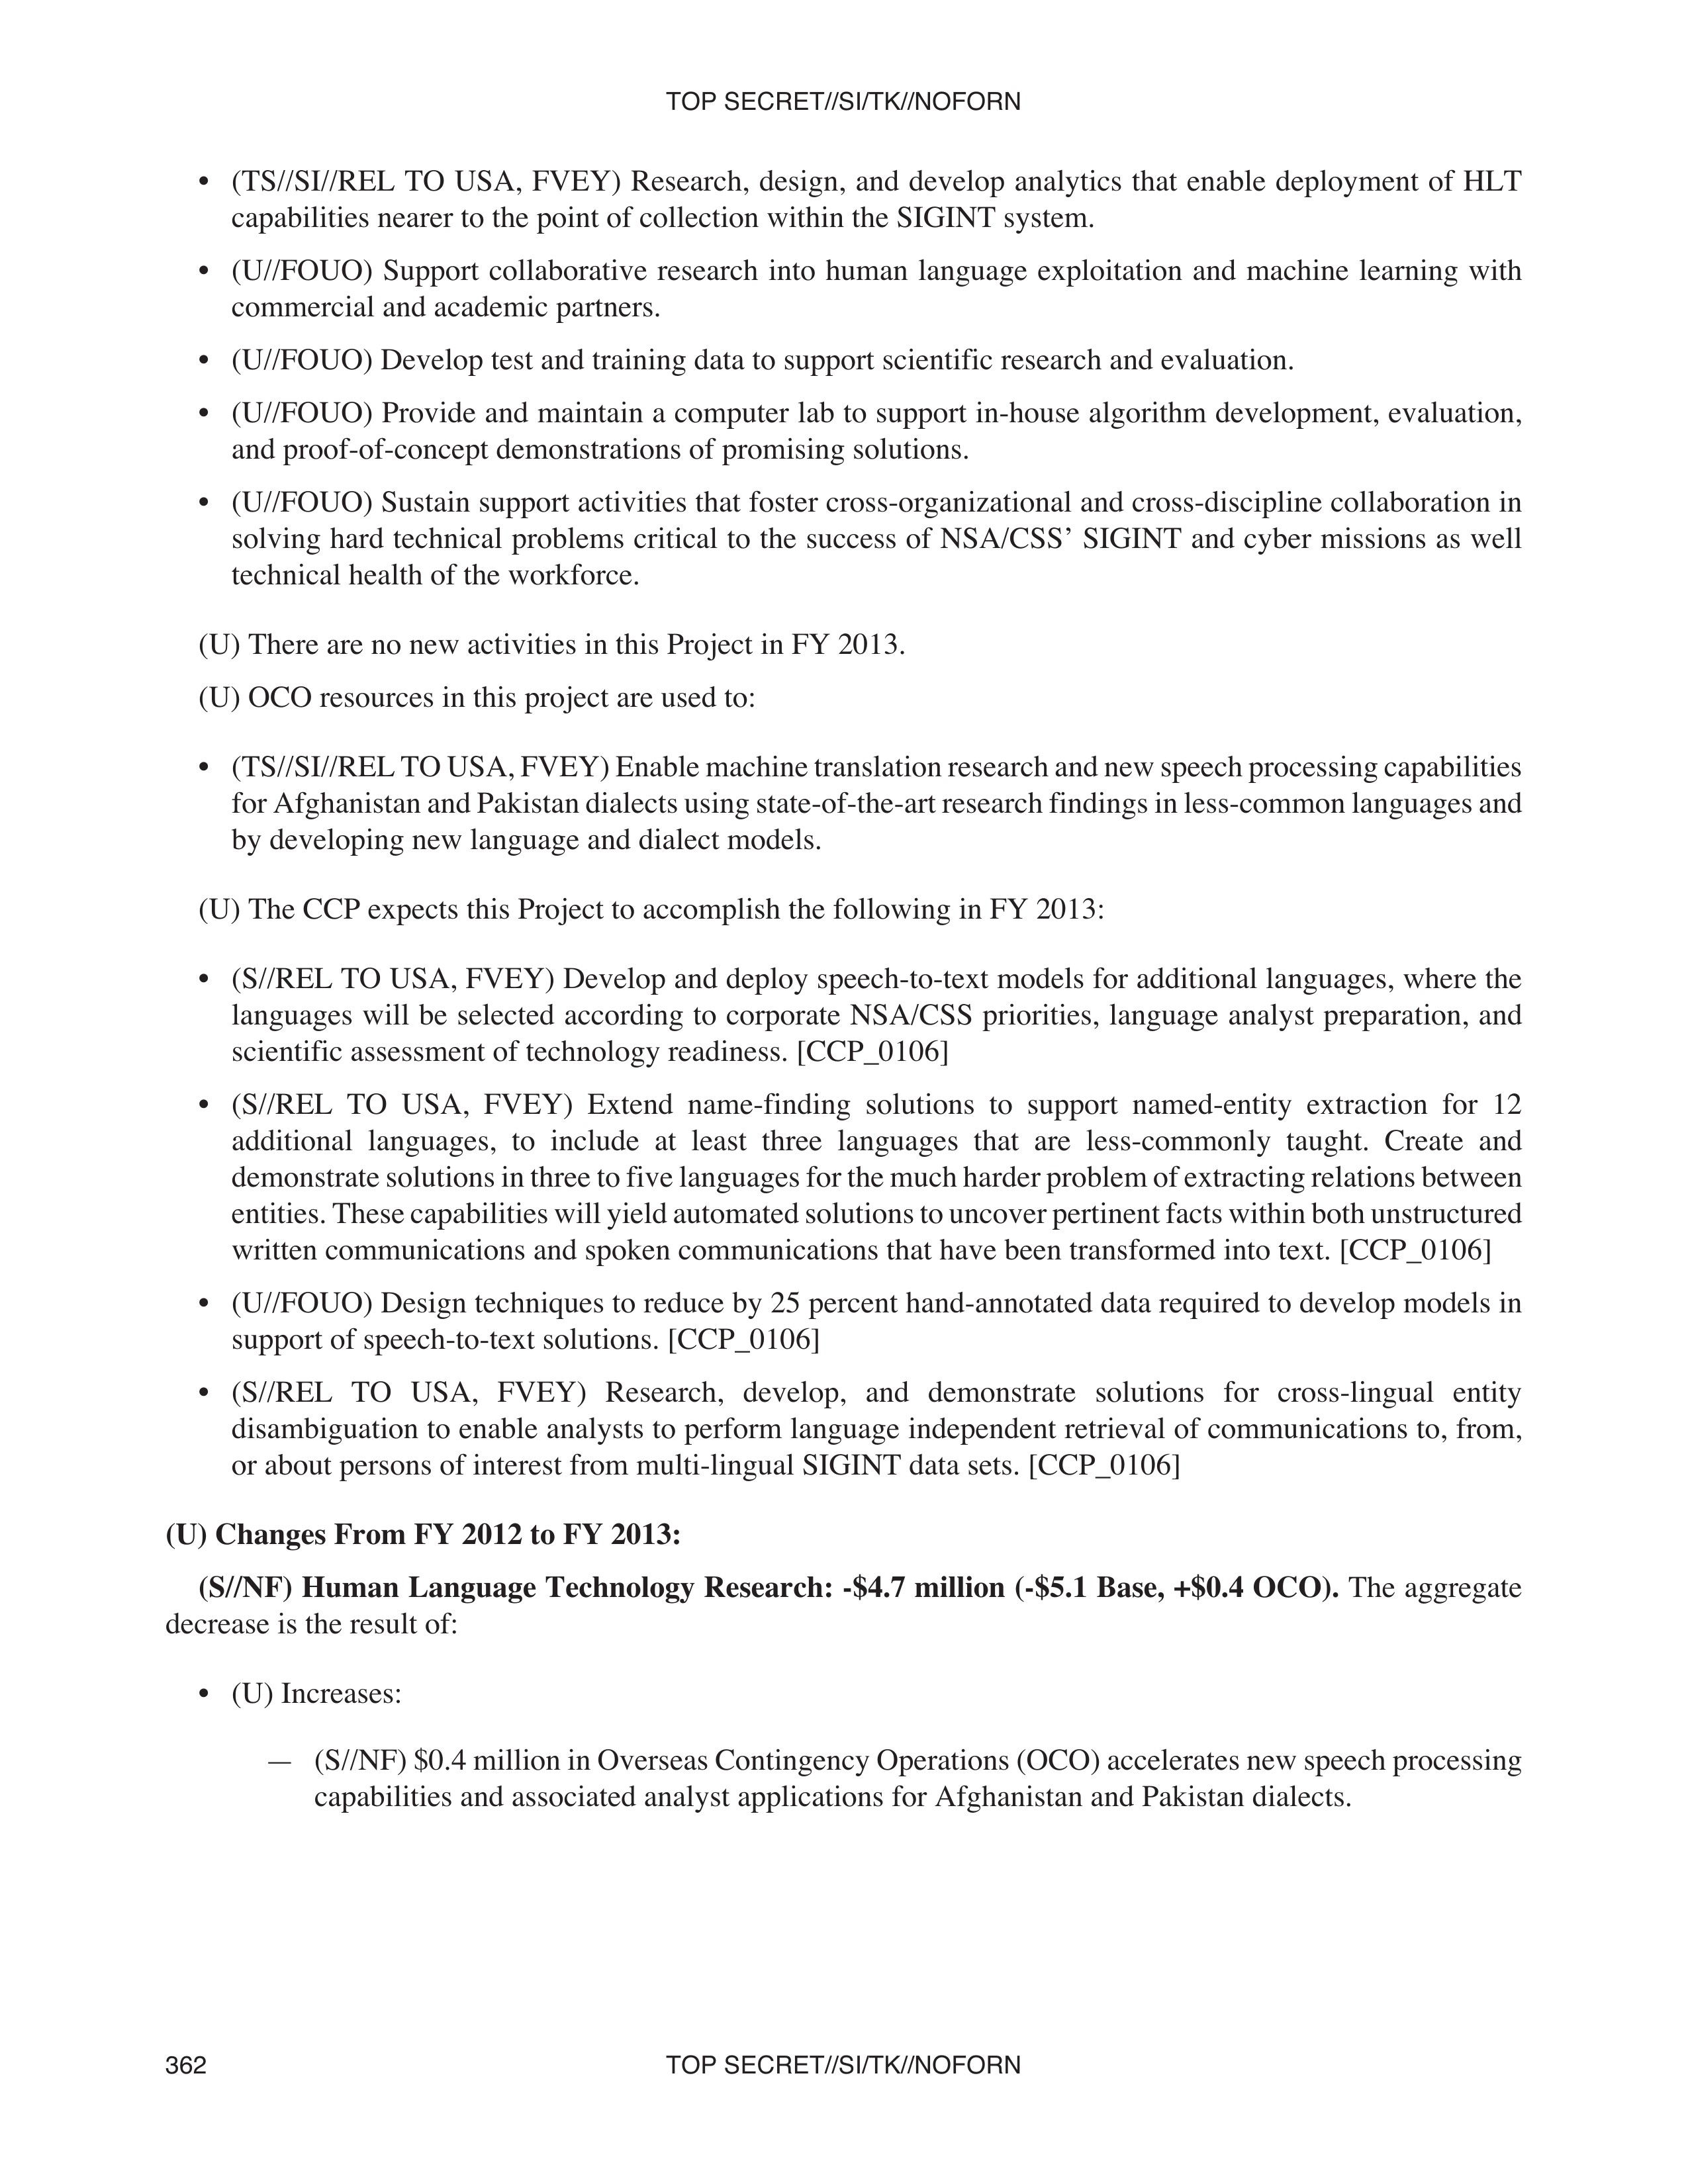
- (TS//SI//REL TO USA, FVEY) Research, design, and develop analytics that enable deployment of HLT capabilities nearer to the point of collection within the SIGINT system.
- (U//FOUO) Support collaborative research into human language exploitation and machine learning with commercial and academic partners.
- (U//FOUO) Develop test and training data to support scientific research and evaluation.
- (U//FOUO) Provide and maintain a computer lab to support in-house algorithm development, evaluation, and proof-of-concept demonstrations of promising solutions.
- (U//FOUO) Sustain support activities that foster cross-organizational and cross-discipline collaboration in solving hard technical problems critical to the success of NSA/CSS' SIGINT and cyber missions as well technical health of the workforce.
(U) There are no new activities in this Project in FY 2013.
(U) OCO resources in this project are used to:
- (TS//SI//REL TO USA, FVEY) Enable machine translation research and new speech processing capabilities for Afghanistan and Pakistan dialects using state-of-the-art research findings in less-common languages and by developing new language and dialect models.
(U) The CCP expects this Project to accomplish the following in FY 2013:
- (S//REL TO USA, FVEY) Develop and deploy speech-to-text models for additional languages, where the languages will be selected according to corporate NSA/CSS priorities, language analyst preparation, and scientific assessment of technology readiness. [CCP_0106]
- (S//REL TO USA, FVEY) Extend name-finding solutions to support named-entity extraction for 12 additional languages, to include at least three languages that are less-commonly taught. Create and demonstrate solutions in three to five languages for the much harder problem of extracting relations between entities. These capabilities will yield automated solutions to uncover pertinent facts within both unstructured written communications and spoken communications that have been transformed into text. [CCP_0106]
- (U//FOUO) Design techniques to reduce by 25 percent hand-annotated data required to develop models in support of speech-to-text solutions. [CCP_0106]
- (S//REL TO USA, FVEY) Research, develop, and demonstrate solutions for cross-lingual entity disambiguation to enable analysts to perform language independent retrieval of communications to, from, or about persons of interest from multi-lingual SIGINT data sets. [CCP_0106]
(U) Changes From FY 2012 to FY 2013:
(S//NF) Human Language Technology Research: -$4.7 million (-$5.1 Base, +$0.4 OCO). The aggregate decrease is the result of:
- (U) Increases:
- (S//NF) $0.4 million in Overseas Contingency Operations (OCO) accelerates new speech processing capabilities and associated analyst applications for Afghanistan and Pakistan dialects.
362
TOP SECRET//SI/TK//NOFORN
TOP SECRET//SI/TK//NOFORN
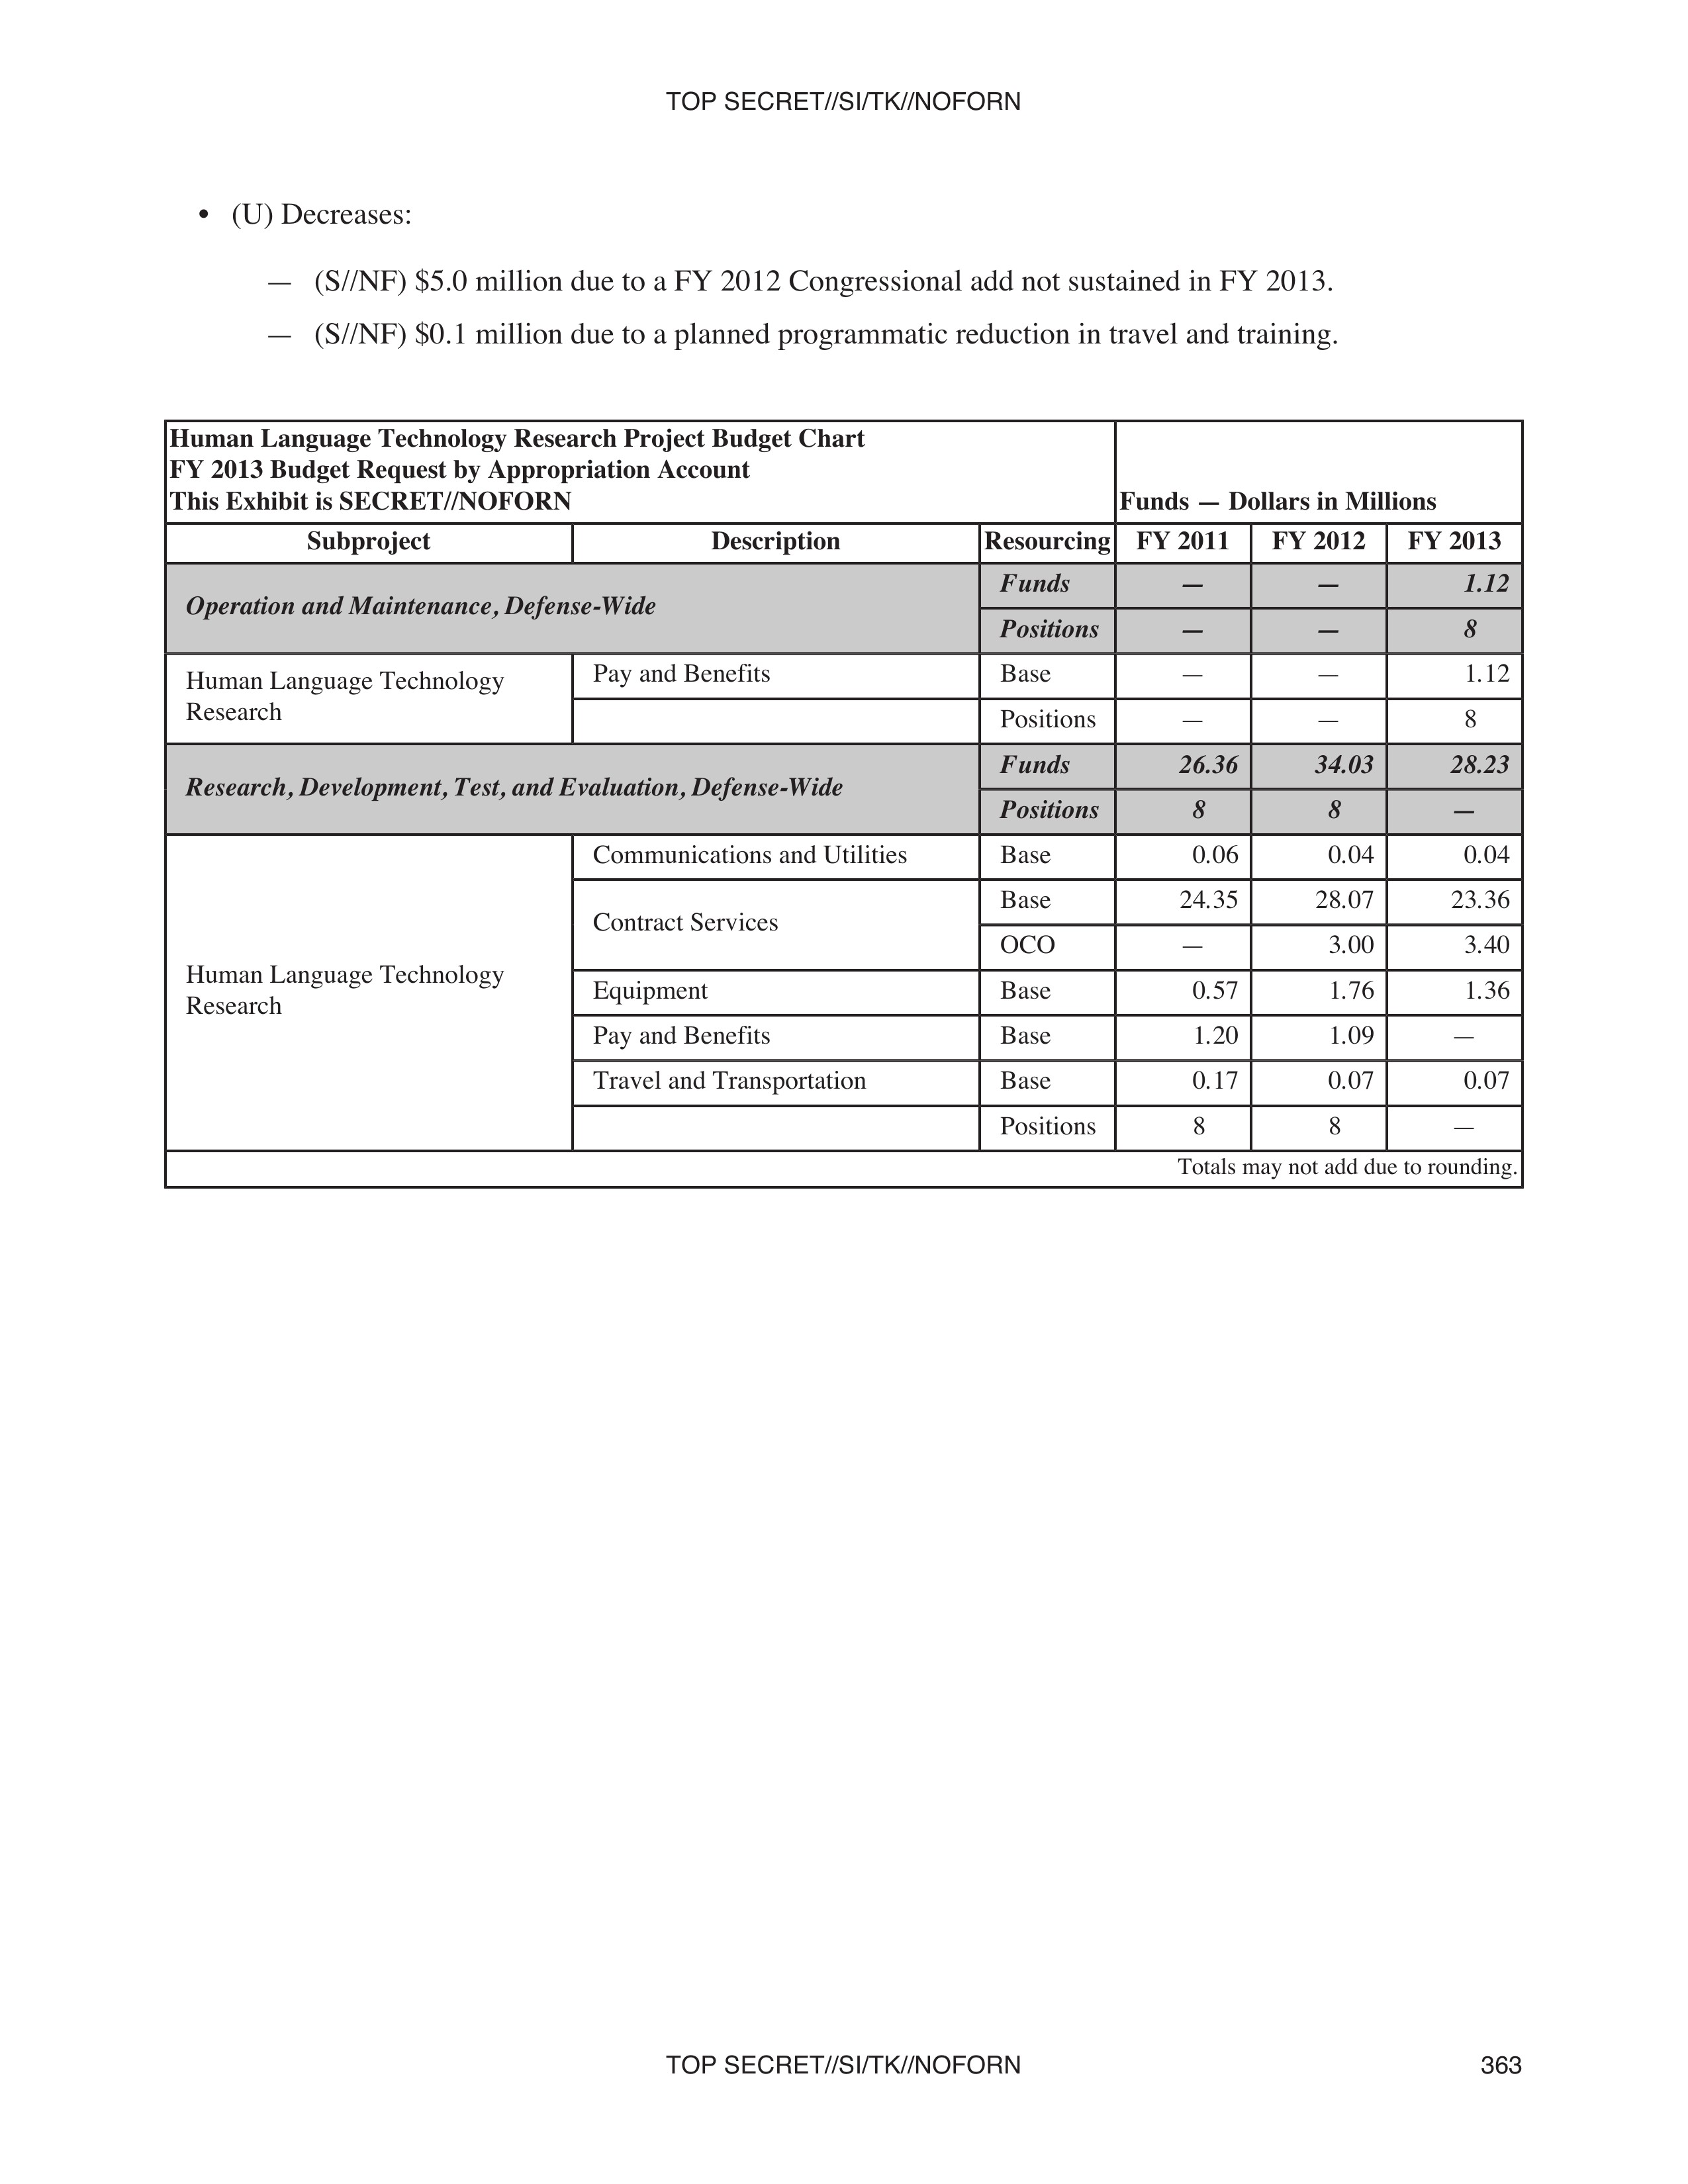
- (U) Decreases:
- (S//NF) $5.0 million due to a FY 2012 Congressional add not sustained in FY 2013.
- (S//NF) $0.1 million due to a planned programmatic reduction in travel and training.
Human Language Technology Research Project Budget Chart
FY 2013 Budget Request by Appropriation Account
This Exhibit is SECRET//NOFORN
| Subproject | Description | Resourcing | Funds FY 2011 | FY 2012 | Funds FY 2013 |
|---|---|---|---|---|---|
| Operation and Maintenance, Defense-Wide | Funds | 1.12 | |||
| Positions | 8 | ||||
| Human Language Technology Research | Pay and Benefits | Base | 1.12 | ||
| Positions | 8 | ||||
| Research, Development, Test, and Evaluation, Defense-Wide | Funds | 26.36 | 34.03 | 28.23 | |
| Positions | 8 | 8 | |||
| Communications and Utilities | Base | 0.06 | 0.04 | 0.04 | |
| Contract Services | Base | 24.35 | 28.07 | 23.36 | |
| OCO | — | 3.00 | 3.40 | ||
| Human Language Technology Research | Equipment | Base | 0.57 | 1.76 | 1.36 |
| Pay and Benefits | Base | 1.20 | 1.09 | — | |
| Travel and Transportation | Base | 0.17 | 0.07 | 0.07 | |
| Positions | 8 | 8 |
Totals may not add due to rounding.
TOP SECRET//SI/TK//NOFORN
363
TOP SECRET//SI/TK//NOFORN
THIS PAGE INTENTIONALLY LEFT BLANK
364
TOP SECRET//SI/TK//NOFORN
Published in the Same Report
(9 documents)
-
For Media Mining, the Future Is Now! SIDtoday [pdf]
A number of new "media mining" tools allow analysts to search intercepted content in near-real time, no matter if text, audio or visual. This includes retroactive word-search in intercepted communications.
People: Picone, Joseph -
For Media Mining, the Future Is Now! (conclusion) SIDtoday [pdf]
In the future, thanks to Human Language Technology (HLT), an analyst will be able to sort through millions on intercepted phone calls each day "and focus on only the small percentage that is relevant". He or she will also be able to get precise answers to queries such as "Where is the mayor of Baghdad?"
People: Picone, Joseph“How the NSA Converts Spoken Words Into Searchable Text” - The Intercept ↗ (2015-05-05) · The Intercept ↗ (2019-05-29) · Froomkin, Dan -
“Black Budget” — FY 2013 Congressional Budget Justification/National Intelligence Program, p. 262 (February 2012) [pdf]
This excerpt from the Fiscal Year 2013 Congressional Budget Justification (the "Black Budget") details the NSA's financial and performance metrics for "Analytics Modernization," specifically focusing on the transition to high-volume, automated speech-to-text systems. It records the decommissioning of legacy voice processing systems (VoiceRT) in favor of more robust, scalable capabilities aimed at rendering millions of intercepted voice files searchable via text queries and paired dialogue transcription.
Programs: VoiceRT -
Classification Guide for Human Language Technology (HLT) Models (May 18, 2011) [pdf]
This document is an NSA administrative policy document that establishes the rules for what information regarding speech analytics remains public versus what must be kept secret. It explicitly confirms that the NSA possesses automated tools for gender, language, dialect, and speaker recognition, as well as speech-to-text and phonetic tokenization. While the existence of these capabilities is unclassified, the specific data used to "train" the models and the actual identity of targeted speakers are protected at the SECRET level.
Programs: HLT -
RT10 Overview [pdf]
This RT10 overview document is a high-level briefing on the implementation of a real-time SIGINT architecture designed to modernize intelligence operations in the Iraq theater, specifically Baghdad. The project aims to replace legacy, "manual-intensive" processes with a "SIGINT Brain"—a distributed database and automated analytic framework capable of processing over 50 million GSM metadata events per day.
Programs: RT10 · OBELISK · WISPYKNIT · VICTORYUNIFORM · JUGGERNAUT · COBRAFOCUS · MATTERHORN · EXPIATION · VoiceRT · GREENDRAGON · TAREX · KEYCARD -
Finding Nuggets -- Quickly -- in a Heap of Voice Collection, From Mexico to Afghanistan SIDtoday [pdf]
A 2011 article by an NSA Texas analyst describing the deployment of Human Language Technology analytics — including speech-to-text, speaker identification, gender recognition and language identification — to Special Collection Service sites in the Americas and to the Afghanistan Remote Operations Cryptologic Center, with operational examples ranging from tunnel detection in Tijuana to intelligence support in Kandahar.
Programs: HLT -
How Is Human Language Technology (HLT) Progressing? SIDtoday [pdf]
This document provides an operational update on the deployment of "HLT Labs"—a specialized suite of voice analytics designed to automate the discovery of intelligence "nuggets" within massive volumes of audio collection. The document highlights successful field applications in Afghanistan, Georgia, Texas, and Latin America, noting that these tools are becoming "force multipliers" that allow linguists to bypass manual listening in favor of automated keyword searching and speaker recognition.
-
Coming Soon! A Tool that Enables Non-Linguists to Analyze Foreign-TV News Programs SIDtoday [pdf]
This document introduces eViTAP (Enhanced Video Text and Audio Processing), a fully automated system designed to monitor and translate international television broadcasts. Primarily aimed at analysts who do not possess specific foreign language skills, the tool leverages automated processing to transform open-source media into actionable intelligence.
-
SIRDCC Speech Technology WG assessment of current STT technology [pdf]
This secret document from the SIRDCC Speech Technology Working Group provides a technical assessment of Speech-to-Text (STT) capabilities for the Security Service (MI5) and GCHQ. The report acknowledges that while automated transcription of intercepted speech remains highly challenging, the technology offers immediate "force multiplier" benefits for specific tasks like identifying spoken telephone numbers or keywords. The Working Group recommends continued investment in bespoke training and a transition toward a common system—specifically the BBN Byblos engine—to facilitate the sharing of classified linguistic models between UK and US agencies.
Programs: BYBLOS
Related Documents
-
“Black Budget” — FY 2013 Congressional Budget Justification/National Intelligence Program, p. 262 (February 2012) [pdf]
This excerpt from the Fiscal Year 2013 Congressional Budget Justification (the "Black Budget") details the NSA's financial and performance metrics for "Analytics Modernization," specifically focusing on the transition to high-volume, automated speech-to-text systems. It records the decommissioning of legacy voice processing systems (VoiceRT) in favor of more robust, scalable capabilities aimed at rendering millions of intercepted voice files searchable via text queries and paired dialogue transcription.
Programs: VoiceRT -
FY 2013 Congressional Budget Justification, Volume I, National Intelligence Program Summary, February 2012 [pdf]
This document outlines the $52.6 billion “black budget,” detailing the structure, priorities, successes, and shortcomings of the 16 U.S. intelligence agencies. It reveals unprecedented insight into funding allocations, operations, and intelligence gaps—including the CIA’s dominant role, expanding cyber operations, and persistent challenges in areas such as North Korea and counterterrorism—while emphasizing the tension between secrecy and public accountability.
-
-
-
Finding Nuggets -- Quickly -- in a Heap of Voice Collection, From Mexico to Afghanistan SIDtoday [pdf]
A 2011 article by an NSA Texas analyst describing the deployment of Human Language Technology analytics — including speech-to-text, speaker identification, gender recognition and language identification — to Special Collection Service sites in the Americas and to the Afghanistan Remote Operations Cryptologic Center, with operational examples ranging from tunnel detection in Tijuana to intelligence support in Kandahar.
Programs: HLT